高级Advanced在线实验室Online lab可打印Printable点子Idea
Transformer:一次注意力怎么算?
Transformer: Calculate One Attention Step
从两维 query、key、value 开始,手算点积、softmax 和加权混合。再遮住未来,理解下一词预测的规则。
Start with two-number queries, keys and values. Calculate dot products, softmax and a weighted mix, then mask the future.
试教点子:已提供活动、学习单和双语指南,尚未标为 Verified。可按学生情况分两次完成。
Teaching idea: activities, worksheets and bilingual guides are available. It is not yet marked Verified; split it into two sessions if helpful.
猜词游戏里,你会寻找有用的线索。Transformer 用数值计算把信息混合起来。这里不猜一整个模型的“心思”,只把一次注意力计算摊开。
In Guess the Word you looked for useful clues. A Transformer mixes information numerically. Let us open up one attention calculation.
开始之前Before you start
区分 query、key、value,计算三个权重的和,并解释因果遮罩为什么不能偷看未来。
Distinguish queries, keys and values, check that weights sum to one and explain why causal masking hides the future.
先学猜词和点积;softmax 可先看比例图,再由大孩子计算。
Start with Guess the Word and dot products; younger learners can inspect proportions before calculating softmax.
一步一步试试看Try it step by step
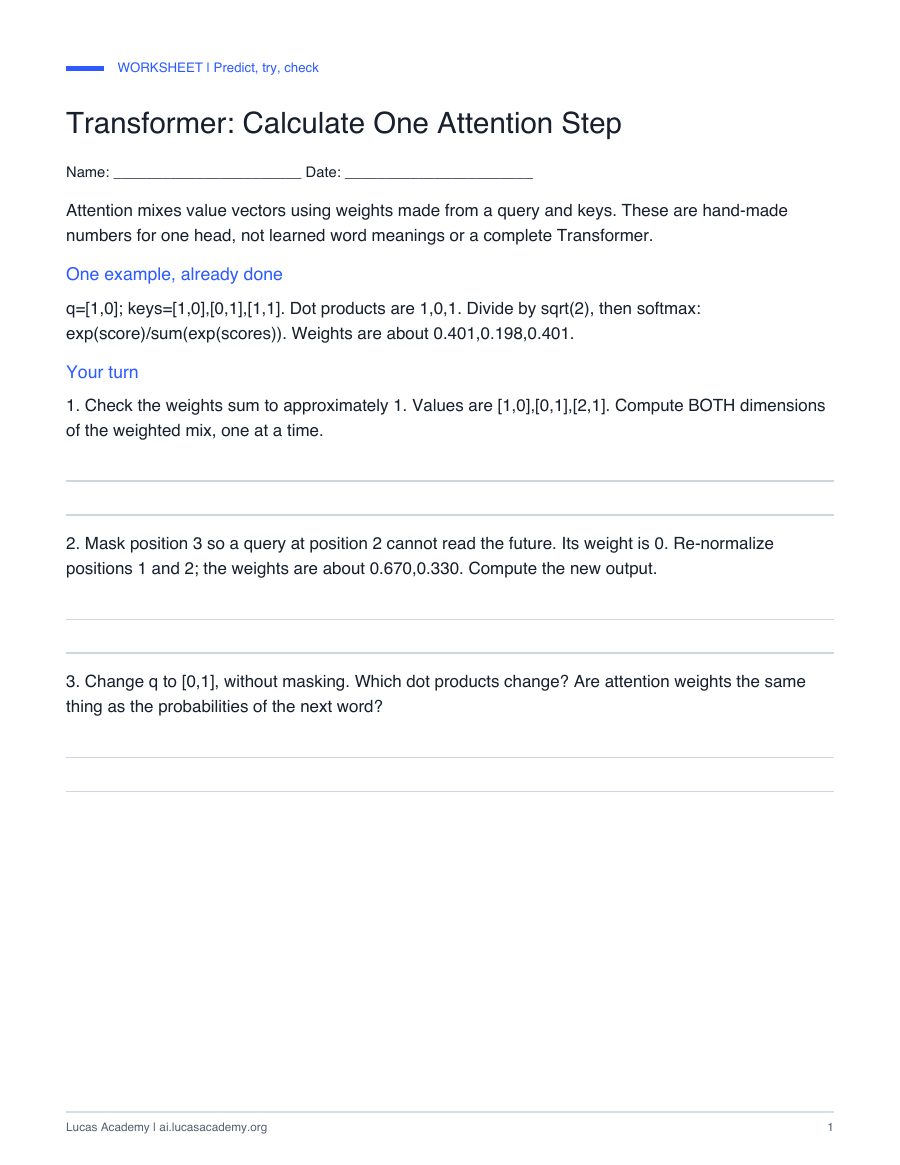
- 先猜:query=[1,0],keys=[1,0]、[0,1]、[1,1]。先不算指数,比较哪两个点积一样。Predict: query=[1,0], keys=[1,0],[0,1],[1,1]. Before exponentials, identify the tied dot products.
- 动手:分数除以 √2,再做 softmax:每个分数取指数,然后除以指数总和。三个权重约为 0.401、0.198、0.401。Try: divide scores by √2, exponentiate each and divide by the total. Weights are about 0.401,0.198,0.401.
- 观察:values=[1,0]、[0,1]、[2,1],用同一权重分别混合每一维,得到约 [1.203,0.599]。权重不是预测词的概率。Observe: mix values [1,0],[0,1],[2,1] with those weights to get about [1.203,0.599]. These are not next-word probabilities.
- 挑战:预测第 2 个位置之后的下一个词时,启用因果遮罩,不能使用第 3 个位置的信息。再把 query 换成 [0,1] 比较。Challenge: when predicting the next token after position two, enable the causal mask so position three is unavailable. Then compare query=[0,1].
一起算一个例子Work through one example
query=[1,0] 与三个 key 的点积为 1、0、1;缩放后为 0.707、0、0.707。softmax 不是把原分数直接除以总和。
Dot products for query=[1,0] are 1,0,1; scaled scores are 0.707,0,0.707. Softmax does not simply divide raw scores by their sum.
先想一想,再看答案Think first, then check
遮住第三个位置后,它的权重是多少?能仅凭注意力最高的词证明模型为什么给出某个答案吗?
What is position three’s weight after masking it? Does the highest attention weight prove why a model answered?
查看参考答案Show the expected answer
第三位权重 0;前两位重新归一化,约 0.670、0.330,输出约 [0.670,0.330]。不能把注意力热图当充分的因果解释。更换 query=[0,1] 时,未遮罩权重约 0.198、0.401、0.401。 query=[0,1] 的点积为 0,1,1。三个 key 完全相同且无遮挡时,权重各为 1/3;序列模型仍需要位置信息。
Position three gets zero; the remaining weights renormalize to about 0.670,0.330, giving output [0.670,0.330]. An attention map is not a sufficient causal explanation. With query=[0,1] and no mask, weights are about 0.198,0.401,0.401. With query=[0,1], dot products are 0,1,1. Three identical keys without a mask give weights of 1/3 each; a sequence model still needs positional information.
这个实验说明了什么What this experiment shows
数值是人为设置的单头示例,没有学到词义。完整 Transformer 还包含学习到的投影、多头、位置表示、前馈层、残差等;这里不训练完整模型。
These are hand-set numbers for one attention head without learned word meanings. A complete Transformer also has learned projections, multiple heads, position information, feed-forward layers and residuals.
学习单Worksheets
学习单用英文,可打印给孩子。教师指南随页面语言下载:当前为中文版。
Print the English worksheets for the children. The guide follows the page language: English is selected.
下载学习单(PDF)Download worksheets (PDF)教师指南(中文 PDF)Teacher guide (English PDF)
视频与文章Videos and reading
- Vaswani et al.: Attention Is All You Need 原始论文,教师参考original paper, teacher reference
- Dive into Deep Learning: Attention Scoring Functions 缩放点积与 softmaxscaled dot products and softmax